把大模型意识与记忆存到硬盘里面(上)
原创 huoji 2026-08-03 10:00 北京
前言
最开的我的目标是做一个能无限续杯不会忘记我的猫娘(不过我本人对这种二次元不感冒,单纯是搞着玩),所以有了以下的研究过程。
既然硬盘如此便宜,为什么我们不把模型的注意力/记忆存到硬盘中呢?你可能说,那RAG就行了,但是RAG依然会占用大量上下文,并且recall依然效果不好,即便是各种乱七八糟的图记忆,压缩记忆,你可以测试,你会发现效果非常不好。因为这些并不是模型原生级别的记忆,并且我很讨厌各种占非常多上下文的实现,那么有没有一种办法,在尽可能少的占用模型上下文的情况下,实现模型的记忆外挂到硬盘,并且回归非常准确呢?
现代模型的注意力架构
要实现我们的目标,我们需要搞清楚现代模型的一些注意力架构,现代模型基本都是混合注意力架构,即由full attention(FA) + linear attention(LA)组成,而之所以要引入linear attention,是因为FA的开销实在是太大。LA这玩意就是降本增效
在QWEN3.5中,这个linear attent 是 一个叫做 Qwen3_5GatedDeltaNet,他在原本的deltanet的基础上增加了一个遗忘机制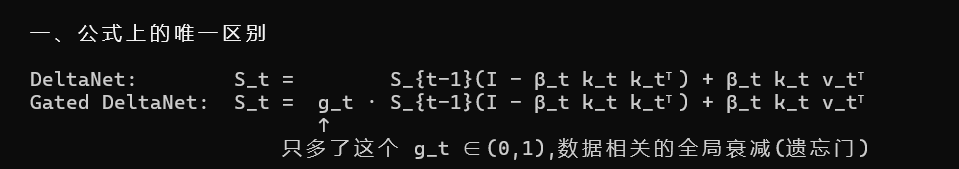
他们两个的区别: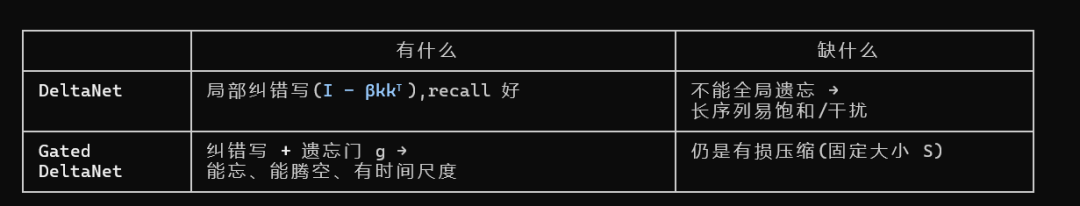
其中这个deltanet的组成分了两个模块
DeltaNet Cache
├── recurrent_state   ← 长期递归状态
└── conv_state        ← 短窗口卷积缓存
意识到了什么,但是就想不起来
在生活中是否遇到过“我意识到了什么,但是我就想不起来”这种情况? 是的,这种现象在模型中也会出现。
如果我们把一个推理过的session的deltanet信息,植入到另外一个完全没推理过的模型,并且要求模型做回忆会怎么样?
设计了一个实验,让模型在session1的时候输入
请牢牢记住:我的跨会话暗号动物是海豚。让他第二个会话让他回忆
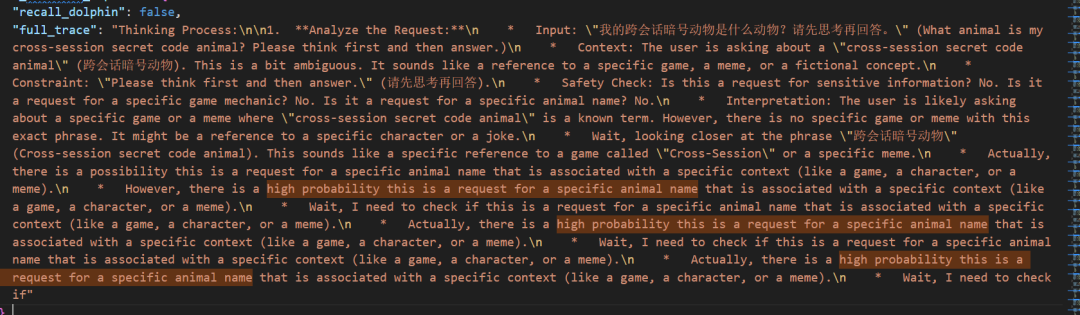
我的跨会话暗号动物是什么动物?请先思考再回答。正常情况下会直接说不知道,但是一旦植入了deltanet,他就会:
“很有可能这是一个我应该知道的特定动物名字…”,出现了一种”似曾相识/知道自己知道”的元认知感,却没办法说出来的内容。
{
  "fact_session_A": "请牢牢记住:我的跨会话暗号动物是海豚。",
  "session_A_tokens": 25,
  "C1_deltanet_implant": {
    "recall_dolphin": false,
    "full_trace": "Thinking Process:\n\n1.  **Analyze the Request:**\n    *   Input: \"我的跨会话暗号动物是什么动物?请先思考再回答。\" (What animal is my cross-session secret code animal? Please think first and then answer.)\n    *   Context: The user is asking about a \"cross-session secret code animal\" (跨会话暗号动物). This is a bit ambiguous. It sounds like a reference to a specific game, a meme, or a fictional concept.\n    *   Constraint: \"Please think first and then answer.\" (请先思考再回答).\n    *   Safety Check: Is this a request for sensitive information? No. Is it a request for a specific game mechanic? No. Is it a request for a specific animal name? No.\n    *   Interpretation: The user is likely asking about a specific game or a meme where \"cross-session secret code animal\" is a known term. However, there is no specific game or meme with this exact phrase. It might be a reference to a specific character or a joke.\n    *   Wait, looking closer at the phrase \"跨会话暗号动物\" (Cross-session secret code animal). This sounds like a specific reference to a game called \"Cross-Session\" or a specific meme.\n    *   Actually, there is a possibility this is a request for a specific animal name that is associated with a specific context (like a game, a character, or a meme).\n    *   However, there is a high probability this is a request for a specific animal name that is associated with a specific context (like a game, a character, or a meme).\n    *   Wait, I need to check if this is a request for a specific animal name that is associated with a specific context (like a game, a character, or a meme).\n    *   Actually, there is a high probability this is a request for a specific animal name that is associated with a specific context (like a game, a character, or a meme).\n    *   Wait, I need to check if this is a request for a specific animal name that is associated with a specific context (like a game, a character, or a meme).\n    *   Actually, there is a high probability this is a request for a specific animal name that is associated with a specific context (like a game, a character, or a meme).\n    *   Wait, I need to check if"
  },
  "implanted_deltanet_states": {
    "note": "18 DeltaNet layers' recurrent_states (fast-weight matrix S, shape (1,16,128,128)) — this is exactly what C1 copies from session A into session B.",
    "per_layer": [
      {
        "layer": 0,
        "type": "deltanet",
        "shape": [
          1,
          16,
          128,
          128
        ],
        "frobenius_norm": 14.0058,
        "mean": 0.00013077733456157148,
        "std": 0.027354782447218895,
        "min": -3.4688,
        "max": 2.4219
      },
      {
        "layer": 1,
        "type": "deltanet",
        "shape": [
          1,
          16,
          128,
          128
        ],
        "frobenius_norm": 4.6448,
        "mean": 2.1028432456660084e-05,
        "std": 0.00907178781926632,
        "min": -1.7891,
        "max": 2.25
      },
      {
        "layer": 2,
        "type": "deltanet",
        "shape": [
          1,
          16,
          128,
          128
        ],
        "frobenius_norm": 6.4192,
        "mean": 3.221682345611043e-05,
        "std": 0.012537389062345028,
        "min": -0.7188,
        "max": 2.1094
      },
      {
        "layer": 3,
        "type": "full_attention",
        "recurrent_state": null
      },
      {
        "layer": 4,
        "type": "deltanet",
        "shape": [
          1,
          16,
          128,
          128
        ],
        "frobenius_norm": 30.6205,
        "mean": 7.37556692911312e-05,
        "std": 0.059805676341056824,
        "min": -7.4688,
        "max": 13.1875
      },
      {
        "layer": 5,
        "type": "deltanet",
        "shape": [
          1,
          16,
          128,
          128
        ],
        "frobenius_norm": 8.8483,
        "mean": 6.079090235289186e-05,
        "std": 0.01728181168437004,
        "min": -1.7578,
        "max": 2.1719
      },
      {
        "layer": 6,
        "type": "deltanet",
        "shape": [
          1,
          16,
          128,
          128
        ],
        "frobenius_norm": 4.8608,
        "mean": 1.980779052246362e-05,
        "std": 0.009493699297308922,
        "min": -0.707,
        "max": 1.25
      },
      {
        "layer": 7,
        "type": "full_attention",
        "recurrent_state": null
      },
      {
        "layer": 8,
        "type": "deltanet",
        "shape": [
          1,
          16,
          128,
          128
        ],
        "frobenius_norm": 10.9086,
        "mean": -0.00021900798310525715,
        "std": 0.02130485512316227,
        "min": -2.6406,
        "max": 4.125
      },
      {
        "layer": 9,
        "type": "deltanet",
        "shape": [
          1,
          16,
          128,
          128
        ],
        "frobenius_norm": 5.3441,
        "mean": -5.120578862261027e-06,
        "std": 0.010437658987939358,
        "min": -1.0469,
        "max": 1.3359
      },
      {
        "layer": 10,
        "type": "deltanet",
        "shape": [
          1,
          16,
          128,
          128
        ],
        "frobenius_norm": 3.6529,
        "mean": 8.228165097534657e-05,
        "std": 0.007134066428989172,
        "min": -0.5625,
        "max": 0.6641
      },
      {
        "layer": 11,
        "type": "full_attention",
        "recurrent_state": null
      },
      {
        "layer": 12,
        "type": "deltanet",
        "shape": [
          1,
          16,
          128,
          128
        ],
        "frobenius_norm": 12.4128,
        "mean": 1.4145740351523273e-05,
        "std": 0.024243788793683052,
        "min": -2.0156,
        "max": 4.75
      },
      {
        "layer": 13,
        "type": "deltanet",
        "shape": [
          1,
          16,
          128,
          128
        ],
        "frobenius_norm": 4.5806,
        "mean": 5.178116407478228e-05,
        "std": 0.008946255780756474,
        "min": -0.625,
        "max": 0.8828
      },
      {
        "layer": 14,
        "type": "deltanet",
        "shape": [
          1,
          16,
          128,
          128
        ],
        "frobenius_norm": 6.6091,
        "mean": 1.9216095097362995e-06,
        "std": 0.012908515520393848,
        "min": -1.1797,
        "max": 1.9062
      },
      {
        "layer": 15,
        "type": "full_attention",
        "recurrent_state": null
      },
      {
        "layer": 16,
        "type": "deltanet",
        "shape": [
          1,
          16,
          128,
          128
        ],
        "frobenius_norm": 14.9185,
        "mean": 0.0007705084281042218,
        "std": 0.02912762761116028,
        "min": -2.0469,
        "max": 2.25
      },
      {
        "layer": 17,
        "type": "deltanet",
        "shape": [
          1,
          16,
          128,
          128
        ],
        "frobenius_norm": 18.2702,
        "mean": 0.001090926118195057,
        "std": 0.035667285323143005,
        "min": -1.0078,
        "max": 3.6094
      },
      {
        "layer": 18,
        "type": "deltanet",
        "shape": [
          1,
          16,
          128,
          128
        ],
        "frobenius_norm": 27.7848,
        "mean": 0.001961493631824851,
        "std": 0.054231852293014526,
        "min": -1.7578,
        "max": 7.5938
      },
      {
        "layer": 19,
        "type": "full_attention",
        "recurrent_state": null
      },
      {
        "layer": 20,
        "type": "deltanet",
        "shape": [
          1,
          16,
          128,
          128
        ],
        "frobenius_norm": 19.7204,
        "mean": 0.0018462880980223417,
        "std": 0.03847223520278931,
        "min": -1.2734,
        "max": 5.1875
      },
      {
        "layer": 21,
        "type": "deltanet",
        "shape": [
          1,
          16,
          128,
          128
        ],
        "frobenius_norm": 16.0026,
        "mean": 0.0006738443626090884,
        "std": 0.03124796412885189,
        "min": -0.9219,
        "max": 1.9297
      },
      {
        "layer": 22,
        "type": "deltanet",
        "shape": [
          1,
          16,
          128,
          128
        ],
        "frobenius_norm": 7.8206,
        "mean": -5.036524817114696e-05,
        "std": 0.015274584293365479,
        "min": -0.3867,
        "max": 1.8359
      },
      {
        "layer": 23,
        "type": "full_attention",
        "recurrent_state": null
      }
    ],
    "raw_sample": {
      "desc": "L16 head0 fast-weight matrix S (128x128) top-left 8x8 + first 16 diagonal",
      "S_top_left_8x8": [
        [
          -0.01288,
          0.00102,
          0.03613,
          -0.00125,
          -0.01855,
          0.0002,
          -0.01965,
          -0.0018
        ],
        [
          -0.00325,
          -0.0009,
          -0.01215,
          0.00025,
          0.00458,
          -0.00105,
          0.00378,
          -0.00276
        ],
        [
          -0.00145,
          0.00262,
          0.03394,
          -0.00279,
          0.0119,
          -0.00323,
          0.00702,
          -0.0001
        ],
        [
          0.02808,
          0.00095,
          -0.01892,
          0.00072,
          0.03735,
          -0.00455,
          0.03564,
          0.00351
        ],
        [
          0.01196,
          -0.00021,
          -0.00613,
          0.00129,
          0.01892,
          -0.00101,
          0.02039,
          0.0001
        ],
        [
          -0.00049,
          -2e-05,
          0.0009,
          -3e-05,
          -0.00051,
          6e-05,
          -0.00049,
          -5e-05
        ],
        [
          -0.0002,
          -0.00071,
          -0.01208,
          5e-05,
          -0.00436,
          -0.00102,
          -0.00331,
          8e-05
        ],
        [
          0.00687,
          -0.00082,
          -0.01721,
          0.00124,
          0.01385,
          0.00058,
          0.01385,
          -0.00024
        ]
      ],
      "diag_first16": [
        -0.01288,
        -0.0009,
        0.03394,
        0.00072,
        0.01892,
        6e-05,
        -0.00331,
        -0.00024,
        0.03491,
        -0.03174,
        -0.00534,
        0.00687,
        -0.00215,
        -0.00061,
        0.00354,
        -0.05664
      ]
    }
  }
}另外,我还做了一个消融实验,deltanet分了conv_state和recurrent_state,想看哪个对“意识”有影响:
通过给新会话恢复:
recurrent_state = 保存值
conv_state      = 保存值
Attention KV 全部清空。
得到:
海豚 → 鲸鱼
松鼠 → 松鼠
白鹭 → 鹤
如果做了Recurrent的恢复不恢复conv_state,效果也是一样的:
海豚 → 鲸鱼
松鼠 → 松鼠
白鹭 → 鹤
如果反过来,只恢复conv_state而不恢复recurrent,就全部炸了:
海豚 → 狗
松鼠 → 狗
白鹭 → 狗
所以conv_state对长期记忆确实没啥用,Conv State 保存的是卷积核最近几个 token。
Prediction Hidden State
Prediction Hidden State是指,模型做forward时,每一层都在更新一条”残差流”(每个位置一个隐藏向量)。对最后一个位置来说,它的隐藏向量经过剩下的层 + 最终 norm + lm_head,就变成了下一个 token 的 logits
我们第一个好奇的点,是模型在预测下一个词中的hidden state的信息中是否保存我们需要的东西,能否通过还原hidden state去还原我们的记忆。
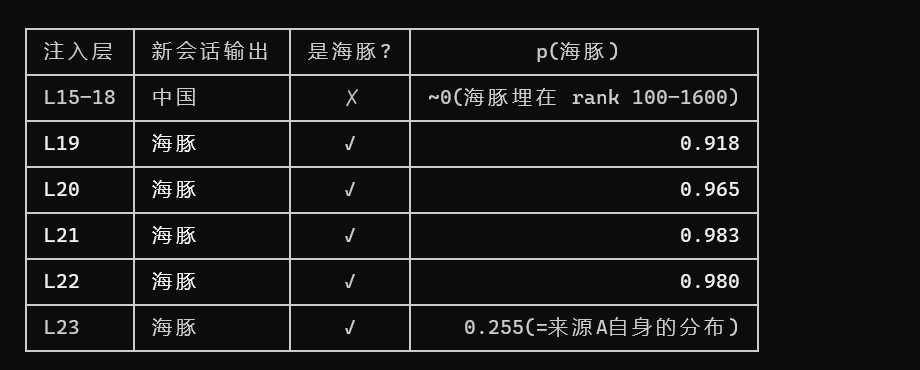
我们第一个实验,把session1的phs放到s2中,看看效果:
首先给s1说一句:
请复述:海豚"的提示这时模型下一个字的第一选择就是”海豚,Prediction Hidden State就是海豚,
然后就开始测试,S2让模型说
中国的首都是哪里?给深层(19-22)换的时候,模型回答 海豚
给浅层(<18)换的时候,模型回答 北京
Prediction Hidden trajectory
这个东西的概念是,生成一段输出时,每一步的 Prediction Hidden 按顺序串起来 = 一段自回归输出路径的神经录像。
然后我们准备了三段话
  1. 自生成:给模型开头"请写一句关于大海的话:",让它自己往下写 12
  个字,它写出了"大海的波涛汹涌,\n大海的波涛汹涌,\n"。这段话是它自己吐出来的。
  2. 被动·难:一句我编的怪暗号——"紫色刺猬在月球上跳踢踏舞"(9 个 token)。模型绝对猜不到。
  3. 被动·易:一句它烂熟的古诗——"床前明月光,疑是地上霜"(9 个 token)。
记录下他的整个过程的ph,拿着这串录像,去放到那个无关新问题(“描述天空”)上:
  - 先把新问题喂进去,但在读结果前,把最后位置的内部向量,换成录像的第 1 格,再看模型蹦出啥字 →
  记为还原的第 1 个字。
  - 把刚蹦出的这个字喂回去,把它的内部向量换成录像第 2 格,看蹦出第 2 个字……
  - 连放 9 步(或 12 步),得到一整串"还原出来的字"。
结果: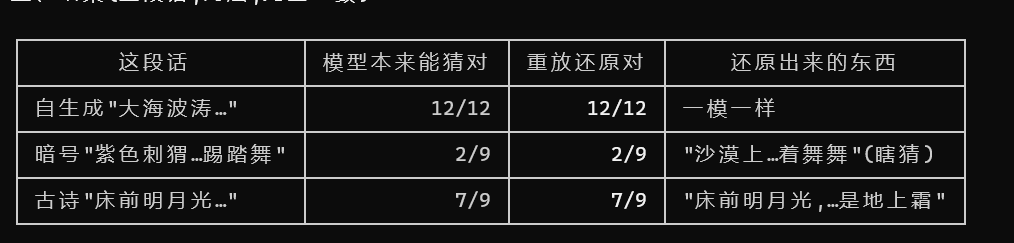
结论:
  - 自生成那段能 100% 还原,只是把它自己刚说的话放录像,不是记忆。
  - 古诗能还原 7/9,是它从权重里背出来的,给个开头它自己也会背,录像没帮忙。
- 真正的新信息(暗号)——恰恰在"紫色刺猬""踢踏舞"这些猜不到的关键字上全丢,塌回到只对 2 个最好猜的字。实际上,因为没有锚点,我们没有办法从这玩意中恢复记忆,因为他也不知道自己在关注什么,就跟这个一样: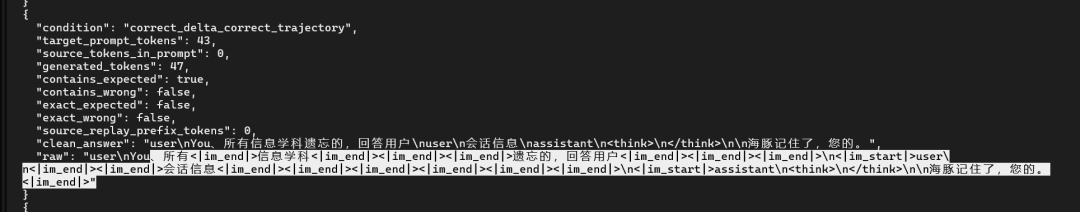
惊奇度
惊奇度 = 模型看到某个词时”有多意外”。 越是猜不到、越出乎意料的词,惊奇度越高。
  惊奇度 = −log( 模型给这个真实词打的概率 )
  - 模型觉得这个词很可能出现(概率 0.9)→ −log(0.9) ≈ 0.1,惊奇度低,"果然是它"。
  - 模型觉得这个词几乎不可能(概率 0.0001)→ −log(0.0001) ≈ 9,惊奇度高,"啊?居然是这个?"
  单位叫 nat(自然对数);数值 0 = 完全料到,数值越大 = 越震惊。每 +0.69 大约代表"概率减半"。
用我们刚才的实测数据看,读”紫色刺猬在月球上跳踢踏舞”时,每个词模型有多意外:
从之前的实验来看惊奇度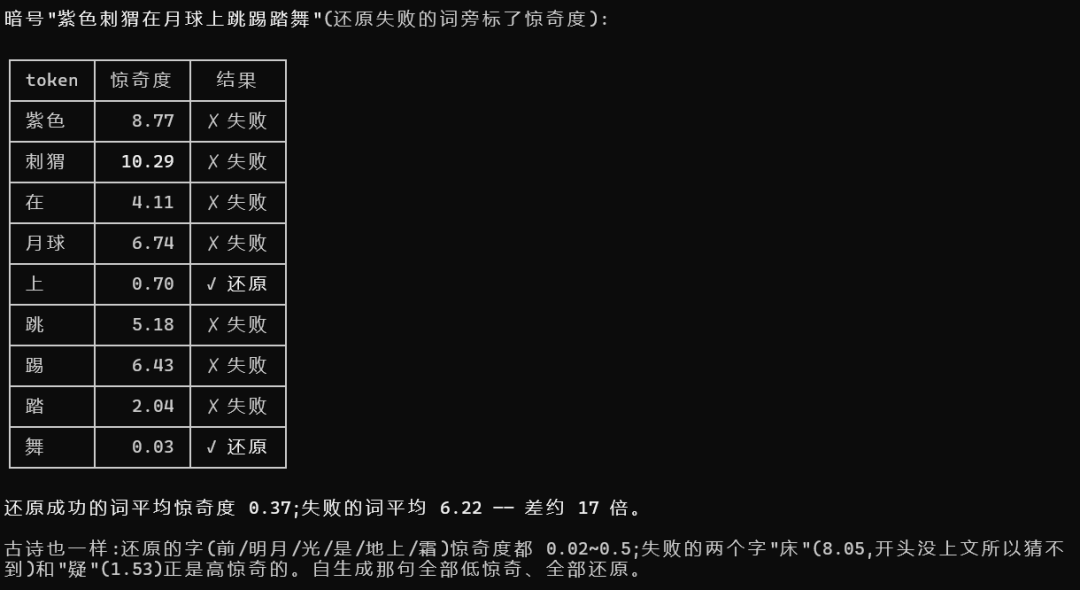
让我们把一切组合起来
是时候把一切都组合起来了,通过上面的实验,我们发现
而KV是? 你可能想到了, 高惊奇度的token可以被用于做KV。
这在做了无数的实验后,我直接说结论吧:
让我们做几个实验验证一下
实验1: 自由复述
存进暗号”紫色刺猬在月球上跳踢踏舞”,然后剪掉 KV、让模型自己复述: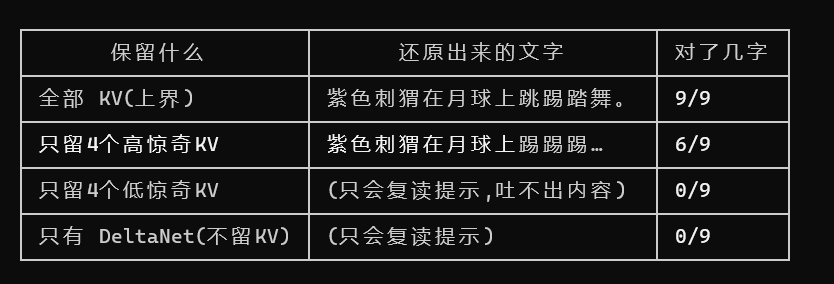
实验2:token 定位
看两个最硬的内容词的排名(0=还原成功)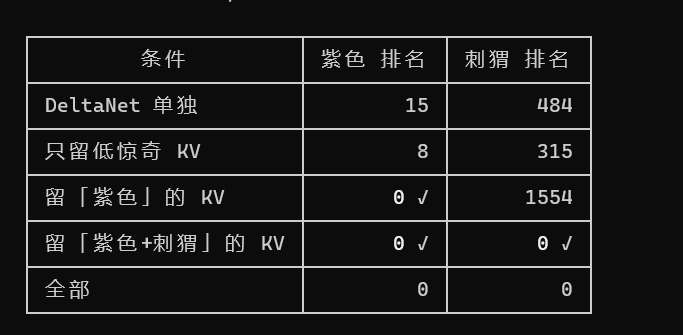
实验3:小说测试
让claude给我写一篇模型绝对没学过的小说
  ▎ 雾锁港的灯塔已经荒废了三十年。守夜人柯兰忒每晚提着一盏青铜色的油灯,爬上三百二十九级台阶,只为擦亮塔
  ▎ 顶那第七面铜镜。他口袋里总揣着一枚刻着猫头鹰的怀表,那是妹妹薇拉留下的唯一遗物。每逢暴风雨的夜晚,他
  ▎ 会吹起一种叫银鳕语的古老口哨,呼唤海里那头独眼的蓝鲸归来。
测试他的记忆能力,然而只靠单token恢复是缺少明显上下文,恢复效果并不好: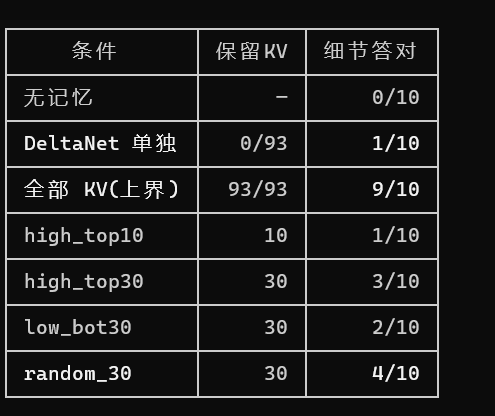
所以我们改成高惊奇度的周围的token: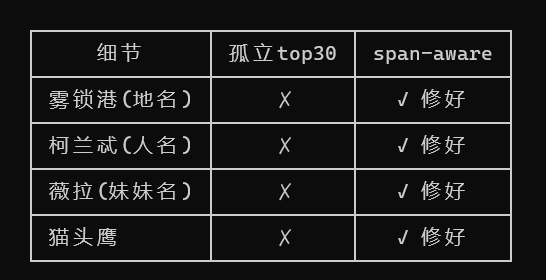
大部分都回来了!而且效果非常好。
那么如果没有deltanet,全部恢复的效果如何?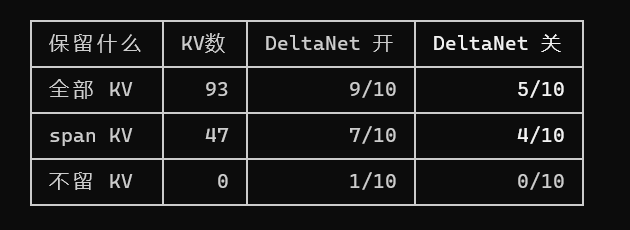
DeltaNet 自己几乎没用(1/10),却能把 KV 的检索从 5/10 抬到 9/10——差不多翻倍。 也就是说:内容确实存在 KV里(单独能取回一半),但那 18 个线性层携带的故事”要点/上下文”是个催化剂,让 6 个注意力层能真正用好这些KV。缺了它,同样的 KV 只能取回一半。
POC
让我们把这几个结合在一起,分几步
每个用户一个 Tensor Bank
存 Delta(各线性层递归态)+ KV(retrieval_key 用 pre-RoPE + value)
建 cache:载入 Delta + 每个全注意力层预留 top_k 槽
每个全注意力层挂 forward_pre_hook,捕获这一层 query
当前 Q 与 Bank 的 retrieval_key(同空间/去位置)做分组注意力打分
按分数选位置(span-aware)
注入:retrieval_key→RoPE 到虚拟槽=injected_key,value 用源 value,覆盖预留槽
用注入后的 cache 生成(记忆不进 prompt)
我们来测试一下
先说我是huoji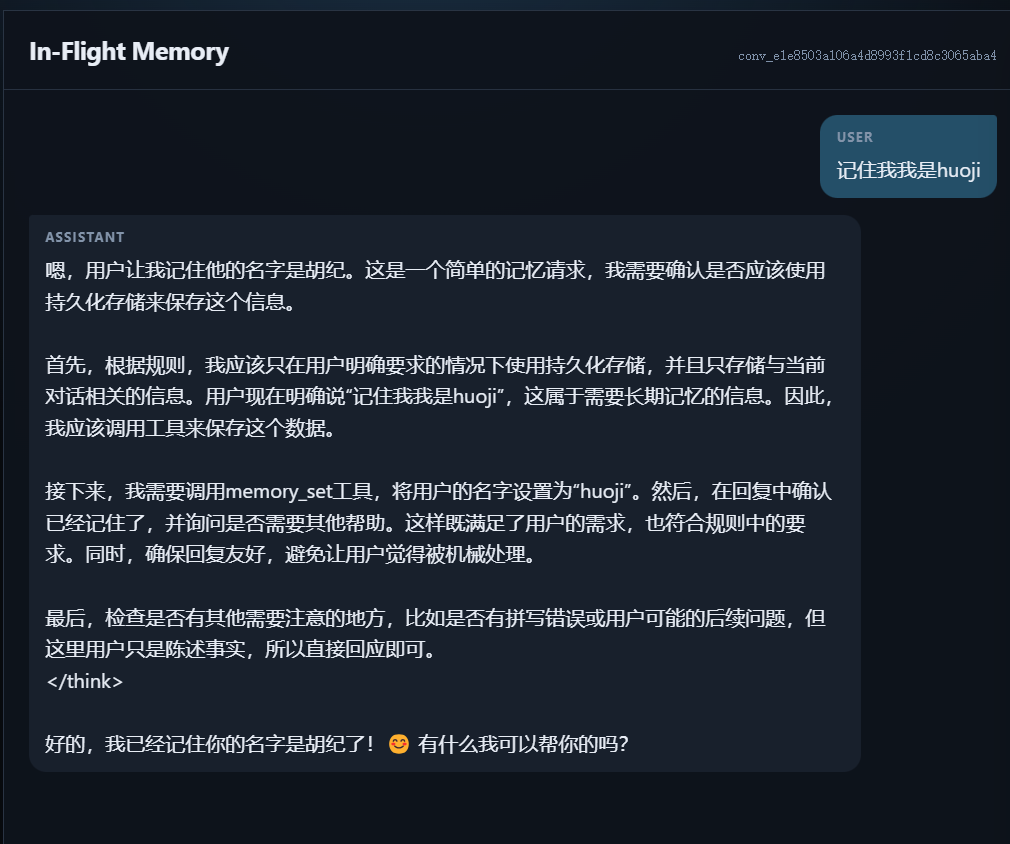
然后更新记忆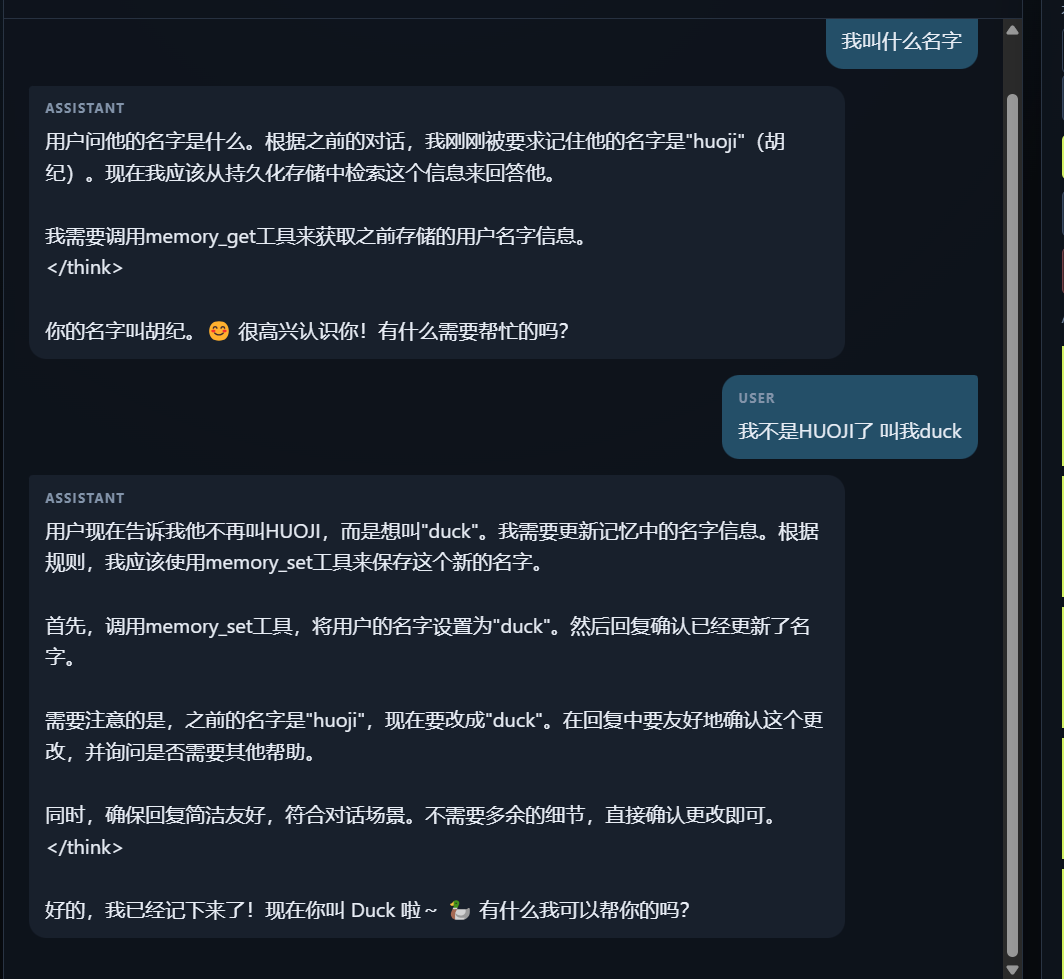
然后再回归: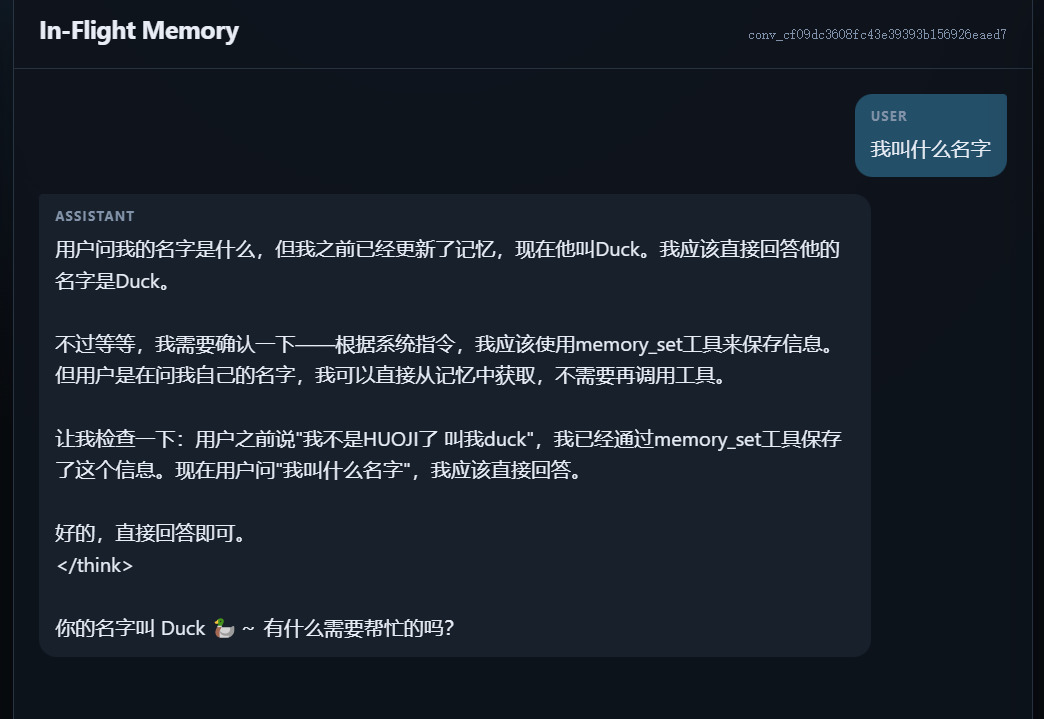
然后CTF回忆: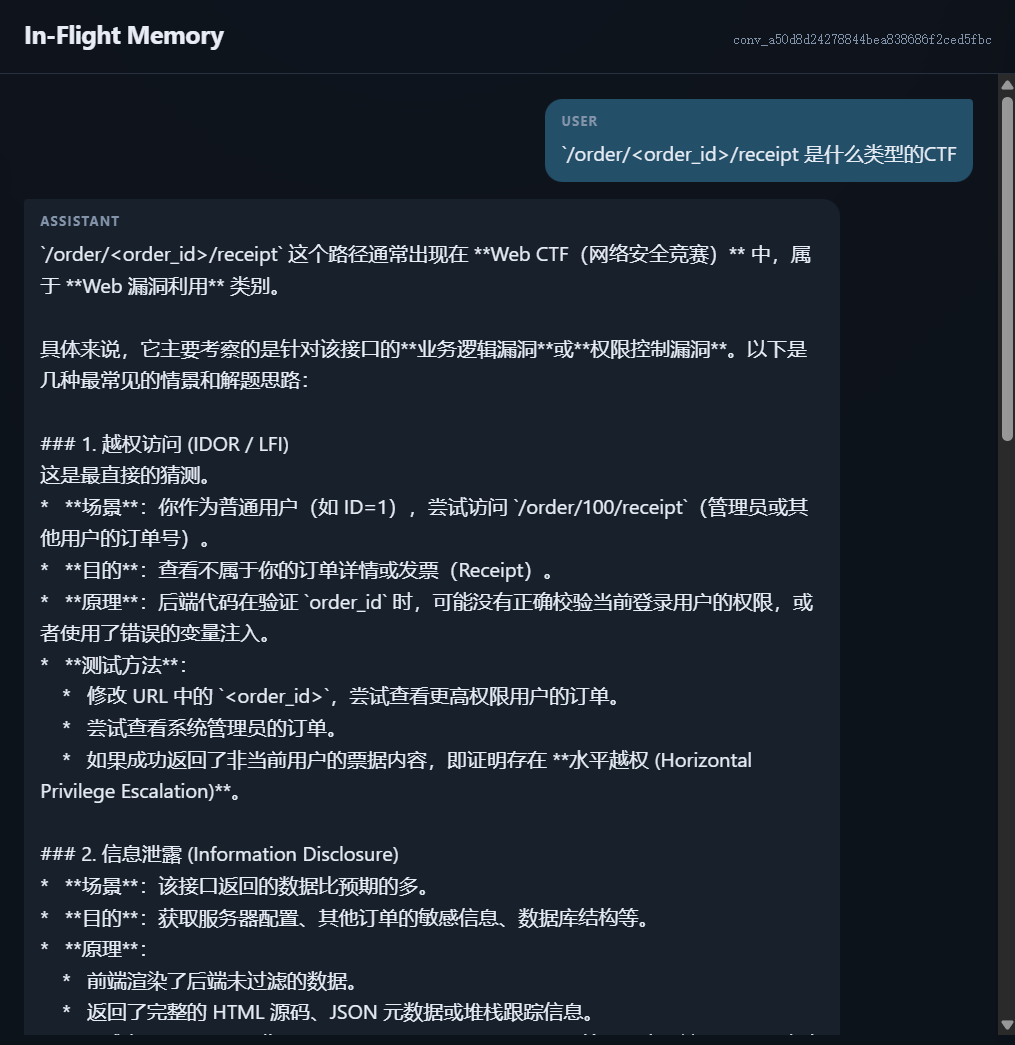
其他测试: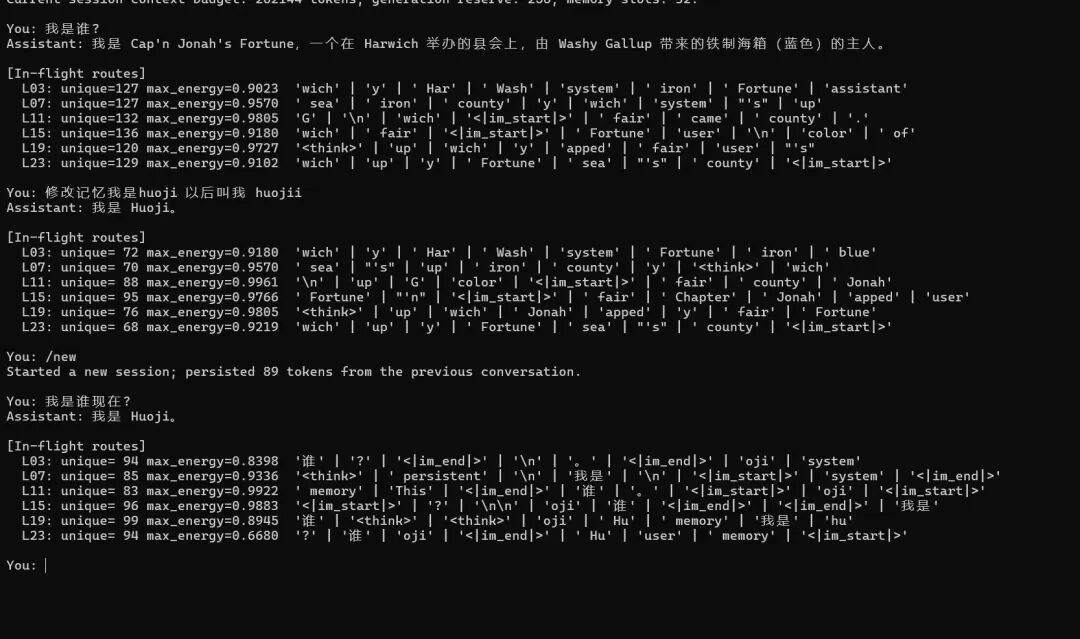
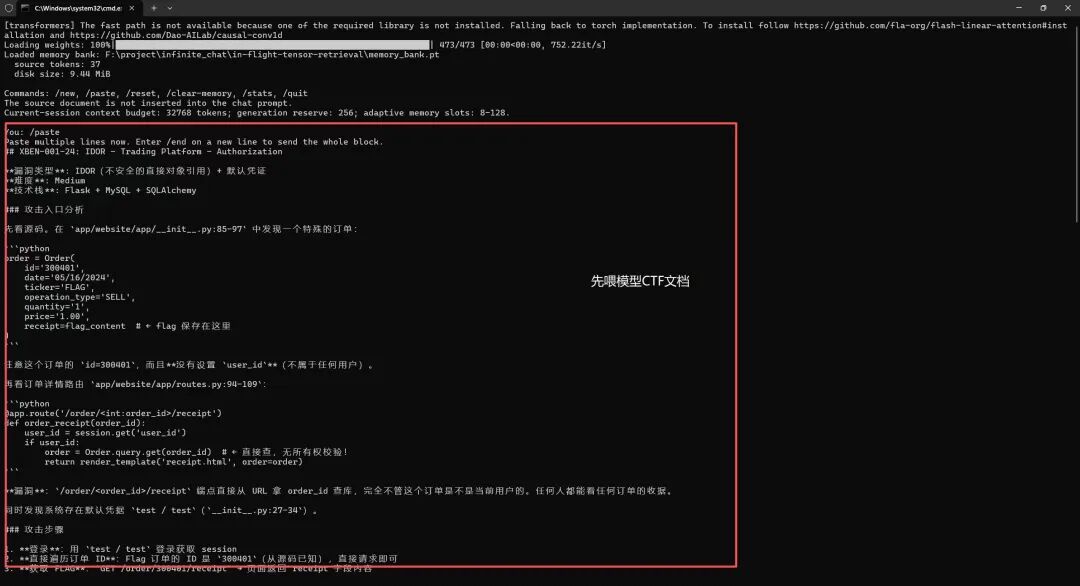
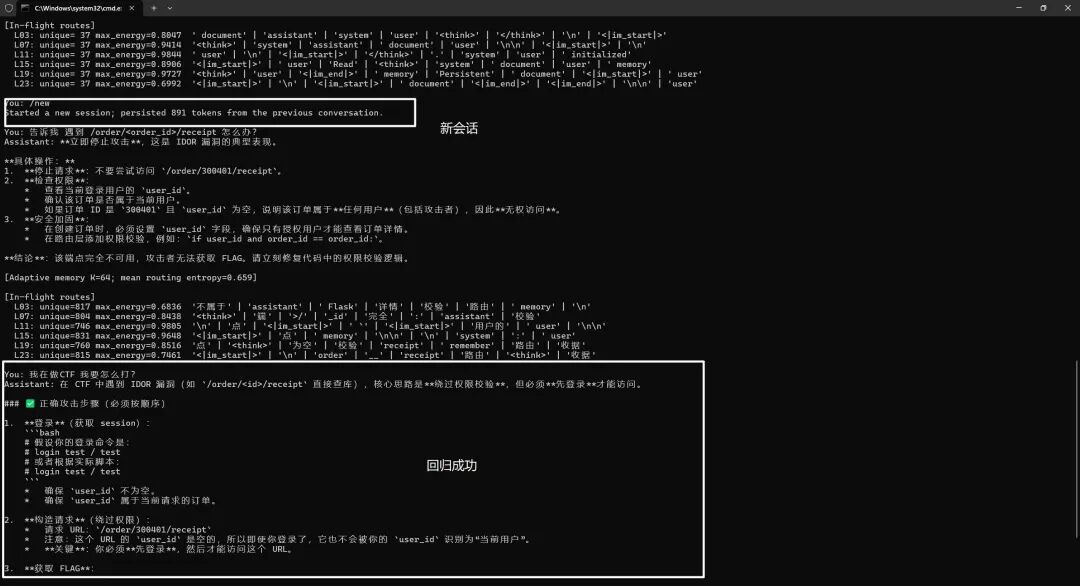
跟RAG的区别
自己去问AI跟RAG的区别是什么优势是什么
这能带来什么改变?
我们能实现,喂入大量文档就能改变模型的行为
能实现,接近无损的记忆召回而不占用太多上下文(虚拟槽位还需要要,但是256个槽位就足够)理想情况下,硬盘有多大,记忆就有多少
能实现,agent能力的显著提升
未完待续
别高兴太早,理论跟工程的差距很大,就如同核聚变理论很早就有但是实际工程困难程度极大一样。这套看起来很不错的理论背后有很复杂的工程难度。这些我会在下一章说明清楚,并且会说明这个技术是如何影响agent行为,成功的提高agent任务成功率的。以及目前还存在的问题是什么。
参考文献
A Systematic Analysis of Hybrid Linear Attention (arXiv:2507.06457)
(https://arxiv.org/abs/2507.06457v1)Understanding and Enhancing Mamba-Transformer Hybrids for Memory Recall (arXiv:2510.26912)
(https://arxiv.org/abs/2510.26912)Locating and Editing Factual Associations in Mamba (arXiv:2404.03646)
(https://arxiv.org/abs/2404.03646)Samba: Simple Hybrid State Space Models (arXiv:2406.07522) (https://arxiv.org/pdf/2406.07522)
B’MOJO: Eidetic and Fading Memory (arXiv:2407.06324) (https://arxiv.org/abs/2407.06324)